35 Asymptotic Distributions
$$
$$
In Chapter 33 and Chapter 34, we learned some strategies for determining the exact distribution of a sum or a mean of i.i.d. random variables, but we also saw their limitations. In many situations, it is not feasible to determine the exact distribution, and the best we can do is to approximate the distribution.
Before we discuss how to approximate distributions, we first recall what it means to approximate a number. One way to make sense of an approximation like \[ a_{1000} = \left(1 + \frac{1}{1000}\right)^{1000} \approx e \tag{35.1}\] is to imagine \(a_{1000}\) as one number in a hypothetical sequence of numbers \[ a_1 = \left(1 + \frac{1}{1} \right)^{1}, a_2 = \left(1 + \frac{1}{2} \right)^{2}, \dots, a_n = \left(1 + \frac{1}{n} \right)^{n}, \dots, \] which converges to \(e\) in the limit as \(n\to\infty\). Therefore, when \(n\) is large, \(a_n\) should be close to \(e\). We are assuming above that \(n=1000\) is large enough for this approximation to be accurate. Indeed, \(a_{1000} \approx 2.717\), whereas \(e \approx 2.718\). In the age before calculators, when evaluating \(a_{1000}\) was not trivial, it was common to simply approximate its value by \(e\).
Now, consider an estimator \(\hat\theta_n\) based on random variables \(X_1, \dots, X_n\). Here, \(n\) represents the sample size. We can imagine \(\hat\theta_n\) as one estimator in a hypothetical sequence of estimators with larger and larger sample sizes: \[ \hat\theta_1, \hat\theta_2, \dots, \hat\theta_n, \dots. \] If we can identify the “limit” to which this sequence “converges”, then we can approximate the distribution of \(\hat\theta_n\) by this limit, provided that \(n\) is large enough. In many modern applications, it is not uncommon for \(n\) to be hundreds, thousands, or even millions, so the approximation can be quite accurate.
It only remains to define what it means for a sequence of estimators to “converge”. We will tackle the more general question of what it means for a sequence of random variables \[ Y_1, Y_2, \dots, Y_n, \dots \] to “converge” to a “limit”. Since estimators are random variables, this theory automatically applies to estimators, but it is more general. In probability and statistics, the study of how random variables behave as \(n \to \infty\) is known as asymptotics. Asymptotics allow us to obtain approximate answers to many questions that would otherwise be intractable.
35.1 Convergence in Distribution
Suppose \(Y_1, Y_2, \dots\) are random variables that can be described by their CDFs \(F_1(y), F_2(y), \dots\), respectively. What does it mean to say that the distribution of \(Y_n\) can be approximated by \(F(y)\) as \(n\) gets large? The next definition provides an answer.
We could have stated Definition 35.1 in terms of convergence of PMFs or PDFs, but it is possible for a sequence of discrete random variables to converge to a continuous distribution or a sequence of continuous random variables to converge to a discrete distribution.
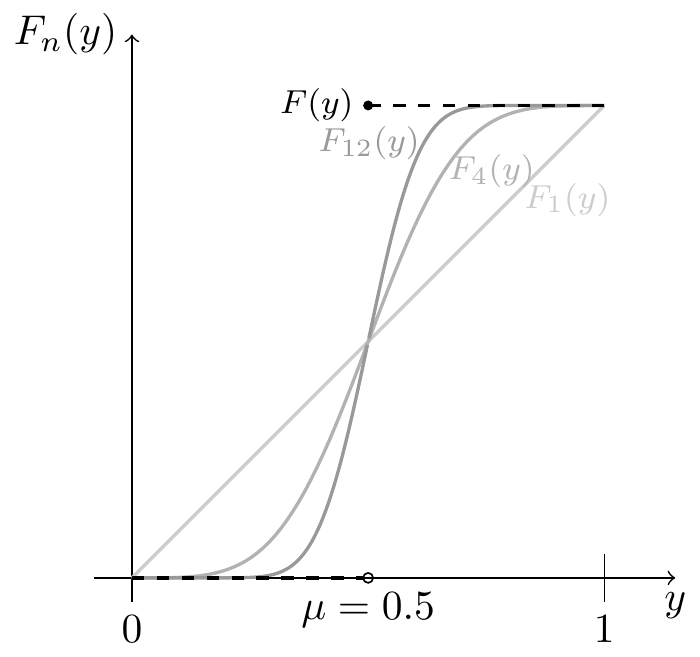
The Law of Large Numbers provides an example of the latter situation. Let \(X_1, \dots, X_n\) be i.i.d. random variables, and let \(Y_n \overset{\text{def}}{=}\bar X_n\) be their sample mean. Figure 35.1 shows the situation where \(X_i\) is \(\textrm{Uniform}(a= 0, b= 1)\). Although each \(Y_n\) is continuous, the limiting distribution \(F(y)\) is discrete, representing the constant “random variable” \(\mu\).
Now, we will prove that the phenomenon illustrated in Figure 35.1 holds generally for i.i.d. random variables with any distribution (with finite variance).
We now have two statements of the Law of Large Numbers: Theorem 28.2 says that \(\bar{X}_n\) converges in probability to \(\mu\), while Theorem 35.1 says that \(\bar{X}_n\) converges in distribution to \(\mu\). What is the difference? In general, the two modes of convergence are distinct. However, in the case where the limit is a constant, convergence in probability and convergence in distribution are equivalent.
Because convergence in probability and convergence in distribution are equivalent when the limit is a constant, Theorem 28.2 and Theorem 35.1 are one and the same.
The Law of Large Numbers provides reassurance that the sample mean \(\bar X_n\) is a reasonable estimator of \(\mu\). Although we saw in Example 32.4 that \(\bar X_n\) may not always be the “best” estimator, \(\bar X_n\) will approach \(\mu\) as the sample size \(n\) increases. This property is known as consistency.
35.2 Convergence in Distribution with MGFs
In the examples so far, the sequence of random variables \(Y_1, Y_2, \dots\) converged in distribution to a constant. Convergence in distribution is more interesting when the limiting distribution is not degenerate.
For example, the code below shows the PMF of a \(\text{Binomial}(n, p)\) random variable \(X_n\). Try increasing \(n\)—what appears to be the limiting distribution?
Although \(X_n\) is discrete for all \(n\), this sequence of random variables appears to “converge” to a normal distribution, which is continuous! However, more work is needed to make this statement precise. Notice that the center of the distribution is drifting towards \(\infty\) as \(n\) increases. This is because the mean \(\text{E}\!\left[ X_n \right] = np\) is increasing. Notice also that the spread of the distribution increases as \(n\) increases. This is because the variance \(\text{Var}\!\left[ X_n \right] = np(1-p)\) is also increasing. Clearly, \(X_n\) diverges as \(n\to\infty\).
In order to make the convergence statement precise, we standardize the random variables, \[ Z_n \overset{\text{def}}{=}\frac{X_n - \text{E}\!\left[ X_n \right]}{\sqrt{\text{Var}\!\left[ X_n \right]}} = \frac{X_n - np}{\sqrt{np(1-p)}}, \] so that each \(Z_n\) has mean \(0\) and variance \(1\). Now, it is plausible that the sequence \(\{ Z_n \}\) converges in distribution. We can show that \(Z_n \stackrel{d}{\to} \textrm{Normal}(\mu= 0, \sigma^2= 1)\), or equivalently that \[ Y_n \overset{\text{def}}{=}\frac{X_n - np}{\sqrt{n}} \stackrel{d}{\to} \textrm{Normal}(\mu= 0, \sigma^2= p(1 - p)) \]
It is virtually impossible to show this directly using Definition 35.1. This is because there is no simple expression for the CDF of the binomial distribution: \[ \begin{align} F_n(y) \overset{\text{def}}{=}P(Y_n \leq y) &= P\left(X_n \leq y \sqrt{np(1-p)} + np\right) \\ &= \sum_{x=0}^{\lfloor y \sqrt{np(1-p)} + np \rfloor} {n \choose x} p^x (1 - p)^{n-x}, \end{align} \] so it is hopeless to find the limit of this expression as \(n\to\infty\).
However, recall from Chapter 34 that distributions can also be uniquely specified by their MGFs. It is often easier to take the limit of the MGF. The following result guarantees that if the MGF has a limit, then this limit is the MGF of the limiting distribution.
Theorem 35.3 was first proved by Paul Levy for characteristic functions (Equation 34.5) and extended by John H. Curtiss (1942) to moment generating functions. Curtiss (1909-1977) was an American mathematician and an early advocate for the adoption of computers. He was one of the founders of the Association for Computing Machinery (ACM), which is the largest professional society for computer science today.
We now apply Theorem 35.3 to show that the \(\text{Binomial}(n, p)\) distribution converges to a normal distribution as \(n\to\infty\).
The upshot of Example 35.1 is that we can use the normal distribution to approximate probabilities for a binomial distribution. We say that the binomial distribution is asymptotically normal.
In the preceding example, we were able to use R to obtain an exact probability (up to floating point precision). Why would anyone settle for an approximation when the exact probability is so easy to obtain? Admittedly, the normal approximation was more important in the age before computers. However, it is still useful today, as shown in the following example.
35.3 Exercises
Exercise 35.1 (Convergence of the discrete uniform distribution) Let \(X_n\) be i.i.d. with PMF \[ f_n(x) = \frac{1}{n};\ \ x=1, 2, \dots, n. \] That is, \(X_n\) is equally likely to be any integer from \(1\) to \(n\). This is called the discrete uniform distribution.
To what named distribution does \(Y_n = \frac{X_n}{n}\) converge?
Exercise 35.2 (Consistency of the normal variance MLE when mean is known) Let \(X_1, \dots, X_n\) be i.i.d. \(\text{Normal}(\mu, \sigma^2)\), where \(\mu\) is known (but \(\sigma^2\) is not). Is the MLE that you derived in Exercise 31.5 consistent for \(\sigma^2\)?
Exercise 35.3 (Consistency of the uniform MLE) Is the MLE that you derived in Exercise 30.5 consistent for \(\theta\)?
Hint: You can obtain an explicit expression for \(P(|\hat\theta_n - \theta| > \epsilon)\).
Exercise 35.4 (MSE and Consistency) Let \(\hat\theta_n\) be an estimator for \(\theta\) such that \[ \text{MSE} = \text{E}\!\left[ (\hat\theta_n - \theta)^2 \right] \to 0 \] as \(n\to\infty\).
Show that \(\hat\theta_n\) is consistent for \(\theta\).
Exercise 35.5 (Asymptotic distribution of the minimum of uniforms) Let \(U_1, \dots, U_n\) be i.i.d. \(\textrm{Uniform}(a= 0, b= 1)\) random variables.
Determine the CDF of \[ Y_n \overset{\text{def}}{=}n \min(U_1, \dots, U_n). \] To what named distribution does \(Y_n\) converge in distribution?
Exercise 35.6 (Poisson approximation to the binomial via MGFs) In Theorem 12.1, we showed that the Poisson distribution was an approximation to the binomial distribution when \(n\) is large and \(p\) is small.
Let \(X_n \sim \text{Binomial}(n, p=\frac{\mu}{n})\). Use MGFs to identify the limiting distribution as \(n \to\infty\).
Exercise 35.7 (Proof of Law of Large Numbers via MGFs) Let \(X_1, \dots, X_n\) be i.i.d. random variables with MGF \(M(t)\).
Prove the Law of Large Numbers (Theorem 35.1) using MGFs and Theorem 35.3.
Exercise 35.8 (Asymptotics for the geometric distribution) Let \(X \sim \text{Geometric}(p=\frac{1}{n})\). Identify the limiting distribution of \(\frac{1}{n} X\) as \(n \to \infty\).
Exercise 35.9 (Normal approximation to the Poisson) Let \(X_n \sim \text{Poisson}(n)\). Show that \[ \frac{X_n - n}{\sqrt{n}} \stackrel{d}{\to} \text{Normal}(0, 1). \]
Exercise 35.10 (Class sections) The number of students \(S\) who enroll in a course is a \(\textrm{Poisson}(\mu=105)\) random variable. The department has decided that if the enrollment exceeds 120, then the course will be divided into two sections (otherwise, there will only be one section). What is the probability that there will be two sections?
- Use R to answer this question exactly.
- Use Exercise 35.9 to come up with an approximate answer.
- How do the two probabilities compare?